My (Chiffon) Nguyen

My (Chiffon) Nguyen she/her

Nguyễn Trà My / 阮沐茶 / 윈자미

AI Research for Broader World & Life-long Learning

I research current and future AI that are safe and empowering for more people. Towards this end, I’m currently interested in the following problems:

My technical work focuses on data and evaluation, to make grounded, predictive, specific claims about AI capability and safety, then improve them.

I’m doing research for Lida Safety. I also contribute to community research, including Cohere Labs Community (leadership & analysis), and BenchFlow (eval infrastructure). Recently I worked on SEATauBench (EMNLP Findings ’26), and CoT monitoring behavior.

I am seeking research Master’s in CS, AI, or NLP for Fall 2027. Open to research collaborations.

Latest updates

see all →

My first co-first-authored paper, SEATauBench, has been accepted to EMNLP Findings 2026.

Selected publications

see all →

MultiCulturalRiddle: A Multicultural Benchmark of Riddles

Tianyi Hu*, Henry Gagnier*, Vinod Anbalagan*, My Chiffon Nguyen*, Pouya Sadeghi*, Farah Abdou*, Abdellah EL MEKKI, Ahanaf Aziz, , Károly Boczka, Julia Kreutzer
Under review at EMNLP MRL Workshop • 2026
Abstract
Capturing how well LLMs can understand and model the diversity of cultures around the globe has increasingly gained importance as LLMs' language coverage has rapidly advanced. However, existing benchmarks are still knowledge- and English-centric with limited coverage and complexity. We propose MultiCulturalRiddle, a benchmark of culturally-grounded riddles, spanning 61 cultures and 51 languages, created in a participatory community effort. These riddles are both hyper-specific to each culture, require factual knowledge, language skills, social knowledge, and strong abductive reasoning skills to solve. We benchmark 24 LLMs with both automatic and human evaluation and release all artifacts publicly.
Evaluation/Benchmarking Multilinguality Cultural Adaptation

GPS-Bench: A Governance Policy Simulator for Automating Policy Analysis

Melanie Bui, My Chiffon Nguyen, Zachary Schlosser, David Williams-King, Linh Le
Under review at AAAI 2027 AI Alignment Track • 2026
Abstract
Governance decisions on artificial intelligence require anticipating both the legislative viability of proposed policies and their downstream effects on heterogeneous stakeholders. Large-language-model (LLM) simulations provide a flexible mechanism for modelling such interactions, but are typically evaluated through qualitative plausibility rather than against observed policy outcomes. We introduce GPS-Bench, an evidence-grounded benchmark and simulation framework for evaluating AI-governance policy forecasts against historical records. GPS-Bench represents each policy as a heterogeneous temporal graph linking antecedent events, policy provisions, actor states, actor actions, world-state changes, and stakeholder impacts; graph components are constructed from public legislative records, voting histories, lobbying disclosures, corporate filings, economic indicators, and expert analyses, with source provenance retained at the node and edge level. We define four linked prediction targets that follow the causal spine of the graph—legislative passage, affected-actor identification, actor-action prediction, and actor-level impact direction—and evaluate them under a temporal split that separates pre-2024 information from policies introduced from 2024 onward, comparing joint LLM prediction, multi-agent simulation, graph neural networks, and graph-structural baselines. Across the four tasks, we find that inference performance depends strongly on both the prediction target and the reasoning strategy. Calibrated probability elicitation substantially improves legislative-passage prediction relative to binary elicitation, although jurisdiction provides a strong baseline. For actor relevance and impact direction, joint inference over the complete grounded policy state consistently outperforms actor-decomposed inference. Within the multi-agent setting, limited communication partially recovers the loss introduced by actor decomposition, but additional rounds do not yield monotonic improvements and targeted communication primarily induces same-stance coalition formation. Graph-structural information improves impact prediction under cross-validation but does not outperform the joint LLM under temporal evaluation. Together, these results suggest that reliable governance simulation depends primarily on evidence-grounded state construction and appropriate inference over that state, rather than on agent complexity alone. We release the corpora, the record-derived actor pools and personas, the quote-verified antecedents, and the evaluation harness.
Evaluation/Benchmarking AI Governance Agent

SEATauBench: Adapting Tool-Agent-User Evaluation Into Low-Resource Southeast Asian Languages

My Chiffon Nguyen*, Aulia Adila*, Saksorn Ruangtanusak*, Kittiphat Leesombatwathana*, Vissuta Gunawan Lim*, Patomporn Payoungkhamdee, Samuel Cahyawijaya
EMNLP Findings • 2026
Abstract
We introduce SEATauBench, the first agentic-focused evaluation framework for sovereign AI development in Southeast Asia, a region of strategic importance with over 700 million people. Despite growing regional evaluation efforts, existing multilingual agents show limited capability when operating in SEA languages, particularly in mixed-language scenarios. Through evaluation across multiple adaptation approaches, we find that while English agentic capabilities transfer to target language responses, performance degrades significantly when context is provided in SEA languages. We propose a translation-based mitigation strategy that preserves entity consistency while enabling agents to leverage English comprehension. SEATauBench establishes a rigorous benchmark for sovereign AI agent assessment, providing diagnostic tools to address capability gaps and support agentic AI development in diverse linguistic communities in the region.
PDF
Evaluation/Benchmarking Agent Multilinguality

Career highlights

see CV →

Latest posts

Miscellaneous

  • My Vietnamese name is ‘Trà My’, which is Camellia japonica (tea flower).

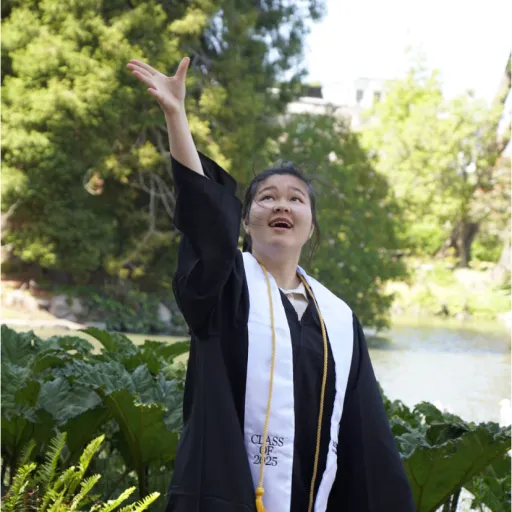
  • I graduated in May 2025 from Minerva University studying Machine Learning & Statistics, with peers from 50+ countries and living in 6 cities as part of its (old) global immersion model: Seoul (South Korea), Taipei, Hyderabad (India), Buenos Aires (Argentina), Berlin (Germany). This experience heavily shapes my worldviews and motivates my research focus in diversity and collaboration.

  • I like reading, cooking, matcha & oolong tea, cycling, teaching, travel (cultural activities & historical museums), event organizing, philosophy, and politics.

  • Other than Vietnamese and English, I speak a bit of Mandarin Chinese (HSK4/B1) and French (A2).

  • My friends asked me to collect tech recommendation in a page: here.

  • Donate to charities if you can afford it! Some options are World Food Programme, Doctors Without Borders, and Giving What We Can.